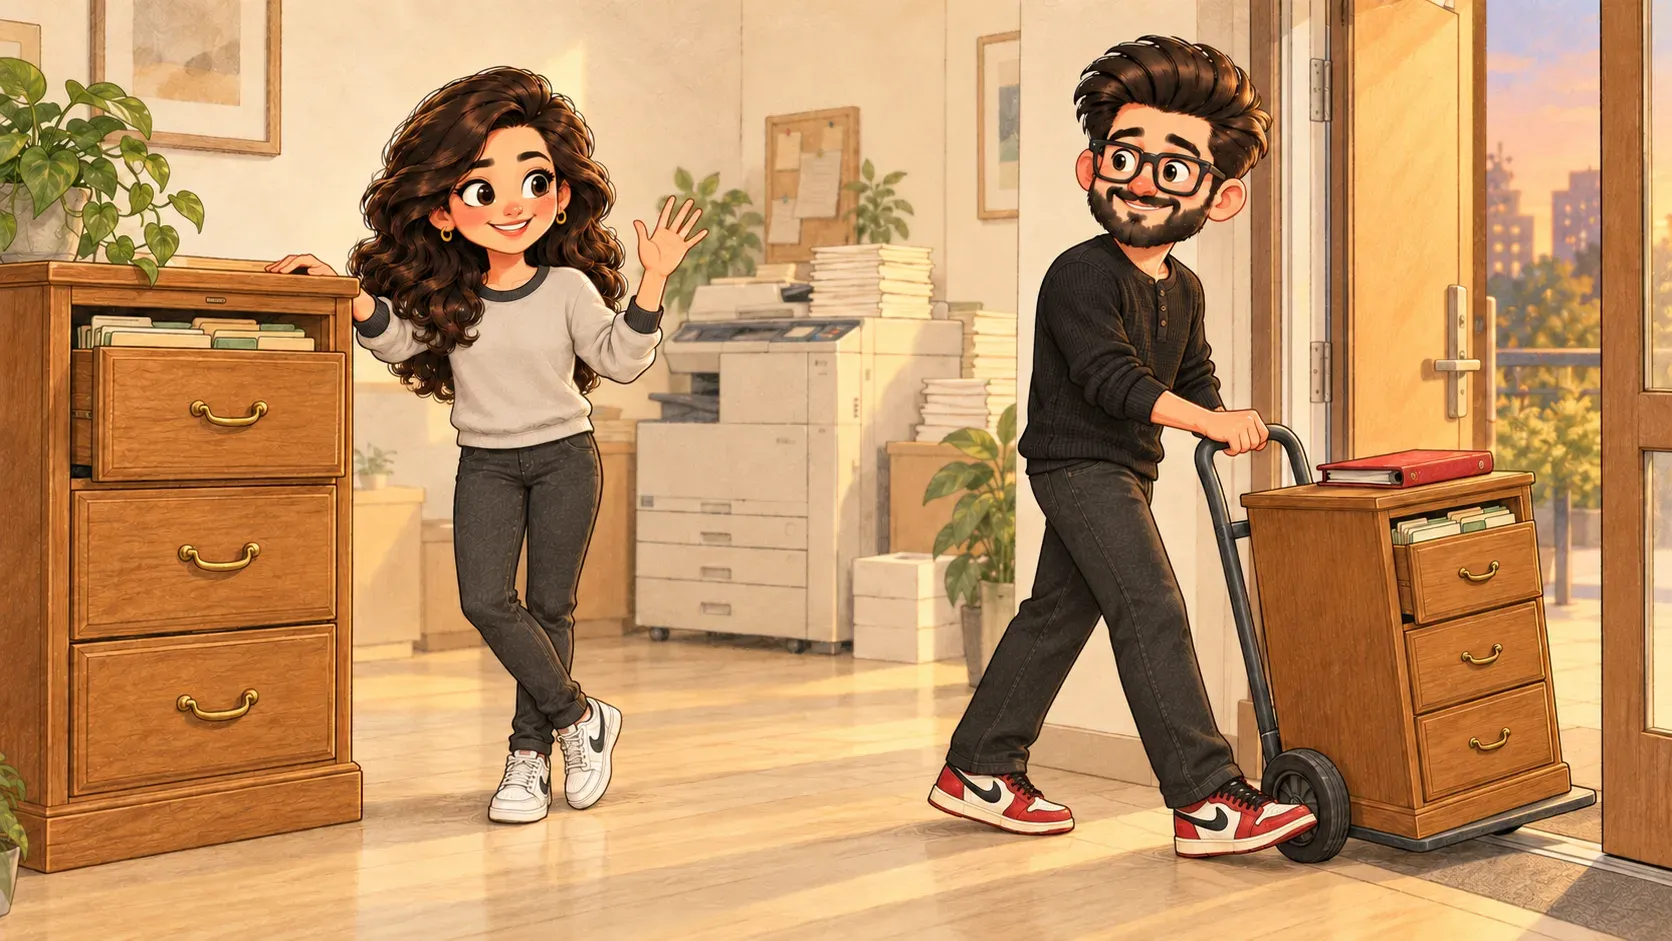

Before you can work on a project, you need it on your own computer. Not just the latest files but the whole cabinet.
Imagine the project’s filing cabinet lives at the office. You want to work from home, so you photocopy the entire cabinet: every folder, every page and every old version in the history drawer. Then you wheel the copy home.
Cloning is that copy: it downloads a full repository, history and all, onto your own computer.
What you get
- every file in the project, ready to open
- the full history, so you can look back without going online
- a link back to where it came from, so you can swap changes later
What it isn’t
It isn’t a one-off download that goes stale. Your copy remembers where it came from. When others add work, you pull it in. When you finish something, you push it back.
It isn’t a fork either. A fork is your own separate copy of someone else’s project, kept online under your name. A clone is the copy on your computer. People often fork a project first, then clone their fork.
Where the comparison breaks down
Photocopying a whole cabinet would take all day. Cloning even a big project usually takes seconds or a few minutes.
How the words fit together
You clone a repository, often from GitHub. You then save changes as commits and use push and pull to keep your copy and the shared one in step.
You only clone a project once. After that, you don't copy it again: you pull to fetch whatever is new.
When you'll hear it
“Just clone the repo and run it.” Copy the project onto your computer, then start it up.
“I cloned it last week.” I already have my own copy, though it may be missing the newest changes.
“Clone it with SSH, not HTTPS.” Use the secure-key way of connecting instead of typing a password.
“Has the new starter cloned the project yet, so they can start on Monday?”

Try it yourselfReady to use it? The exact commands are on my other site, devcmds: Clone a repository ↗
