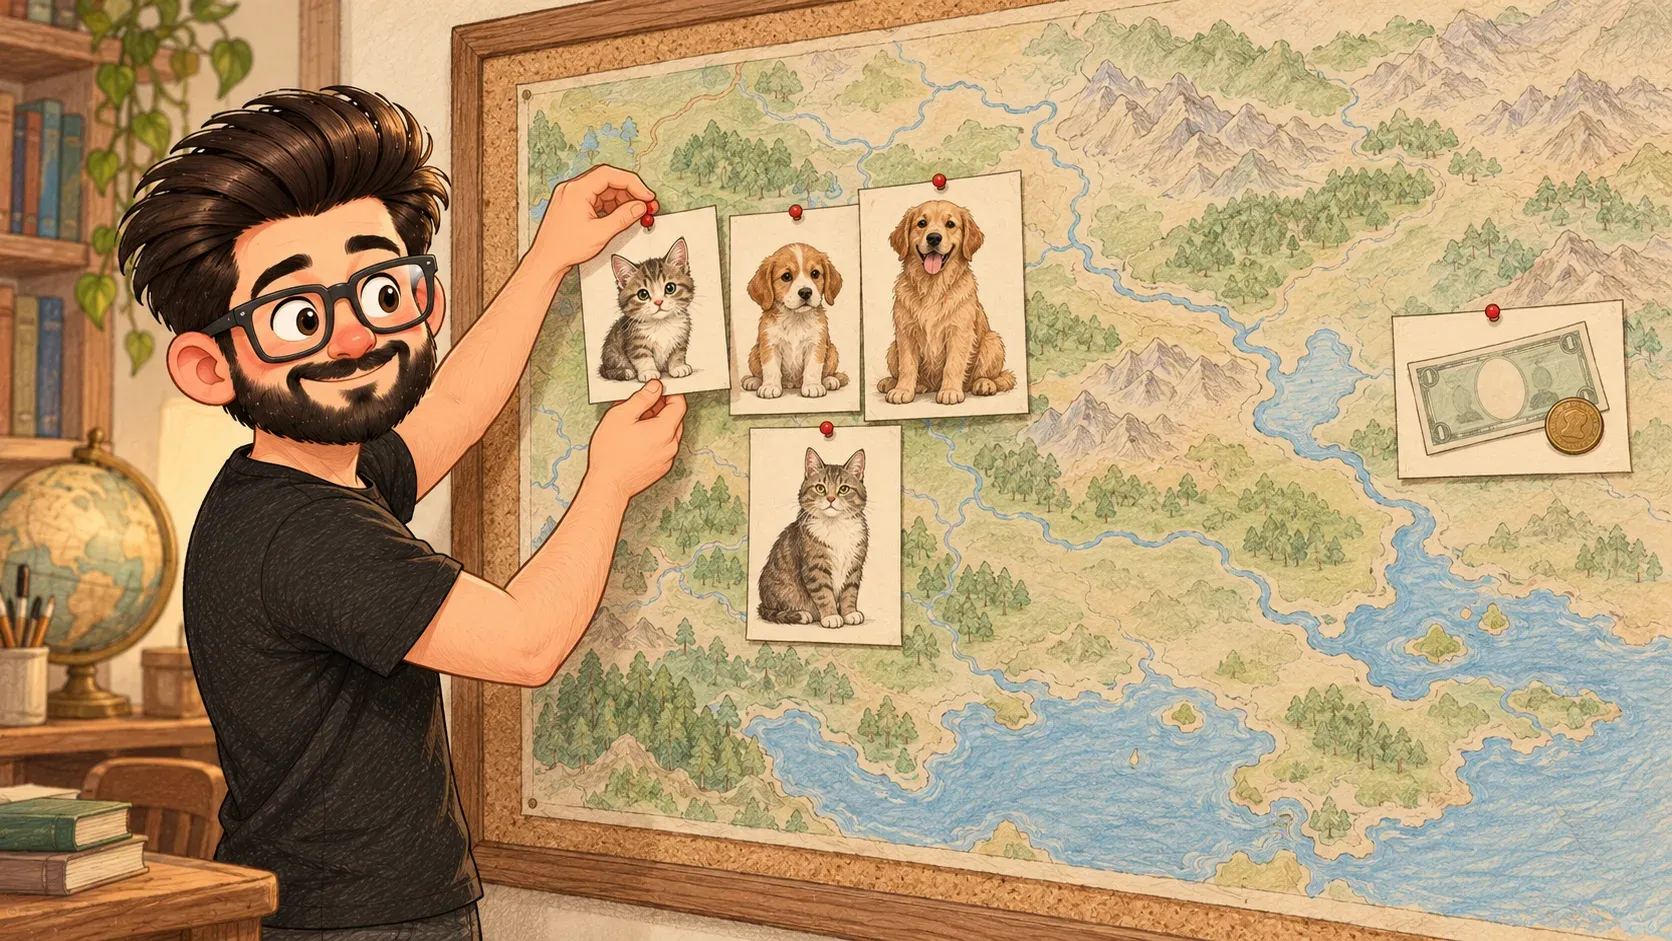

How can a computer tell that “puppy” and “dog” are close in meaning, but “puppy” and “invoice” aren't? It gives each a place on a map.
Picture a giant map where every idea has a spot. “Dog” and “puppy” sit right next to each other. “Cat” is nearby. “Invoice” is miles away in another corner.
An embedding is an idea’s position on that map. It’s a long list of numbers that captures what a word, sentence or document means. Things with similar meanings get similar numbers, so they land close together.
What they’re used for
- search that finds what you meant, not just matching words
- finding the right documents for an AI to read in RAG
- recommending similar songs, products or articles
- grouping customer feedback by topic
How the map is made
An AI model reads the text and works out its position. Nobody draws the map by hand: the model learned which ideas belong near each other from huge amounts of text.
What it isn’t
It isn’t a summary or a keyword. You can’t read an embedding: it’s just numbers. Its only job is to be close to similar things.
Where the comparison breaks down
A paper map has two directions: north-south and east-west. An embedding map has hundreds or thousands of directions, which is how it can capture so many shades of meaning at once.
How the words fit together
Embeddings help RAG find the right documents. They’re made by neural networks, the same family as LLMs.
Embeddings are why AI search can find what you meant, not just the exact words you typed.

When you'll hear it
“We embedded all our documents.” We turned every document into a meaning-map position, so we can search by meaning.
“Use semantic search.” Search by meaning, using embeddings, instead of exact keywords.
“It's stored in a vector database.” The meaning positions are kept in a database built for finding nearby ones fast.
“Would searching our documents by meaning, not just keywords, actually help people find things?”
