
Every new AI model claims to be the best. Evals and benchmarks are the tests that check.
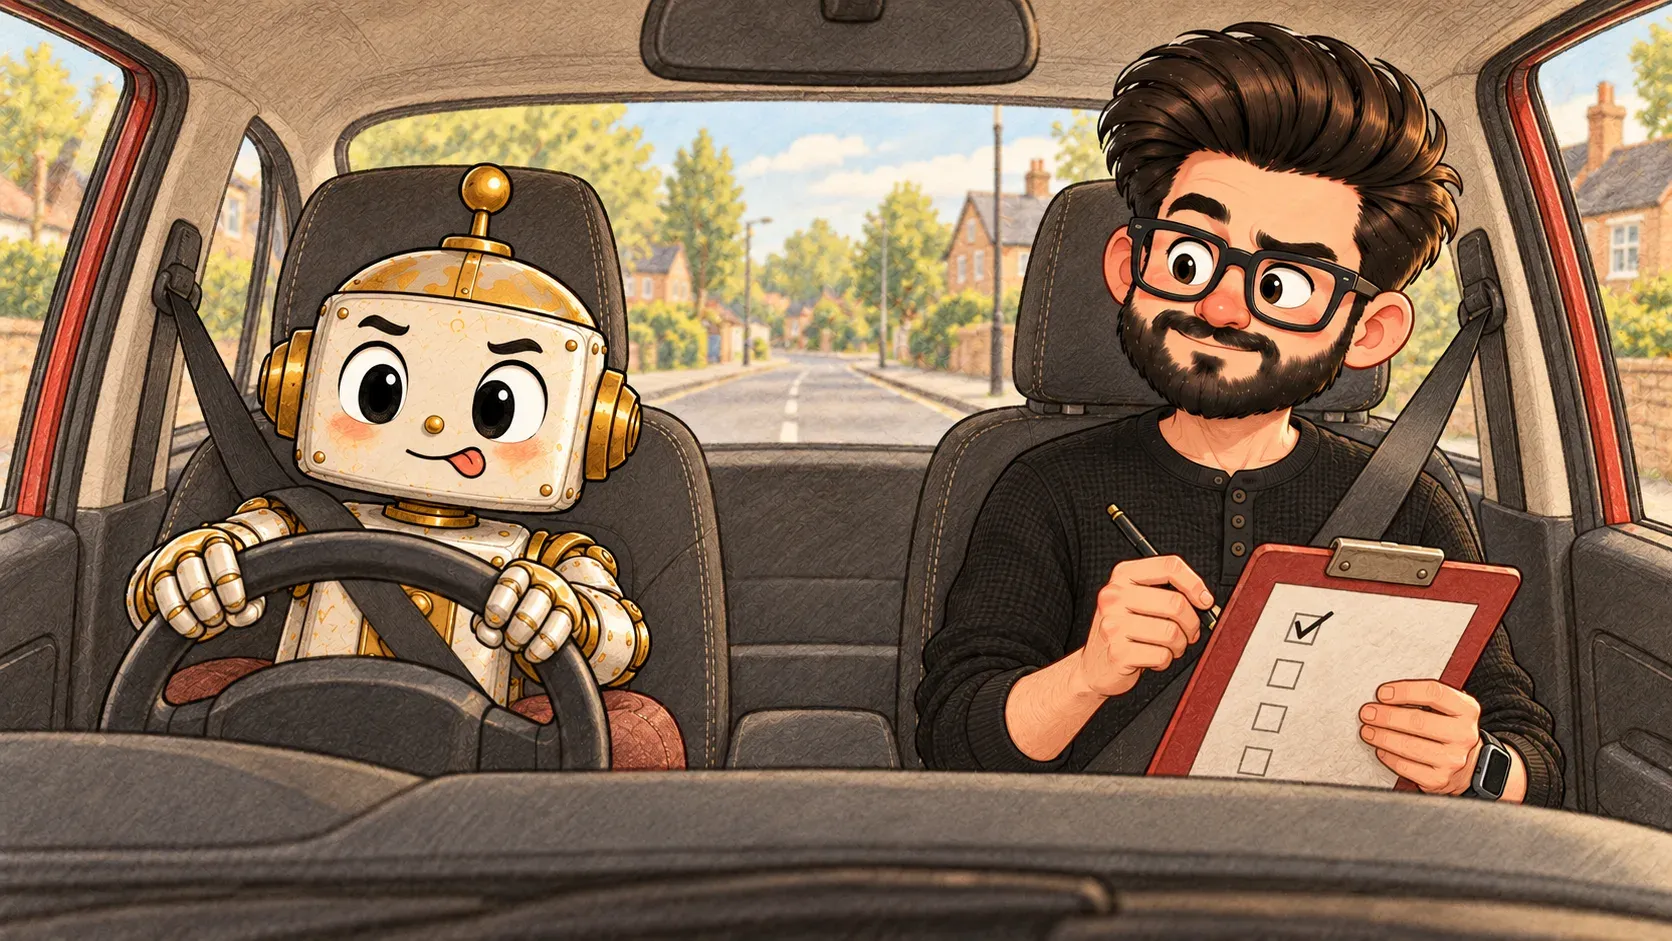
Before you’re allowed on the road alone, you take a driving test. An examiner sits beside you and checks the same things everyone is checked on: parking, junctions and an emergency stop.
AI models get tested the same way. An eval, or benchmark, is a set of test questions used to measure how well an AI model does something. Run the same test on different models and you can compare them fairly.
What they measure
- maths and reasoning problems
- writing and fixing code
- answering exam-style questions
- how often it makes things up (hallucination)
Benchmark or eval?
“Benchmark” usually means a famous public test that everyone uses. “Eval” is broader: any test, including private ones a company writes for its own needs.
What it isn’t
It isn’t proof a model is good at everything. Models can be trained so heavily on popular tests that they score well without being as capable in real use.
Where the comparison breaks down
A driving test is the same for every learner and kept secret beforehand. AI benchmarks are often public, so answers can leak into a model’s training, which can inflate scores.
How the words fit together
Evals compare LLMs after training. Good evals also check for hallucinations and safety, not just right answers.
A model that tops public benchmarks may still be poor at your task. The best eval is a set of real examples from your own work.
When you'll hear it
“It scored top on the benchmark.” It got the best result on a well-known public test.
“We built our own evals.” We wrote test questions from our real work to see which model handles it best.
“The benchmark is saturated.” Every top model scores near full marks now, so the test can't tell them apart.
“Before we choose an AI model, have we tested it on examples of our own real work?”
