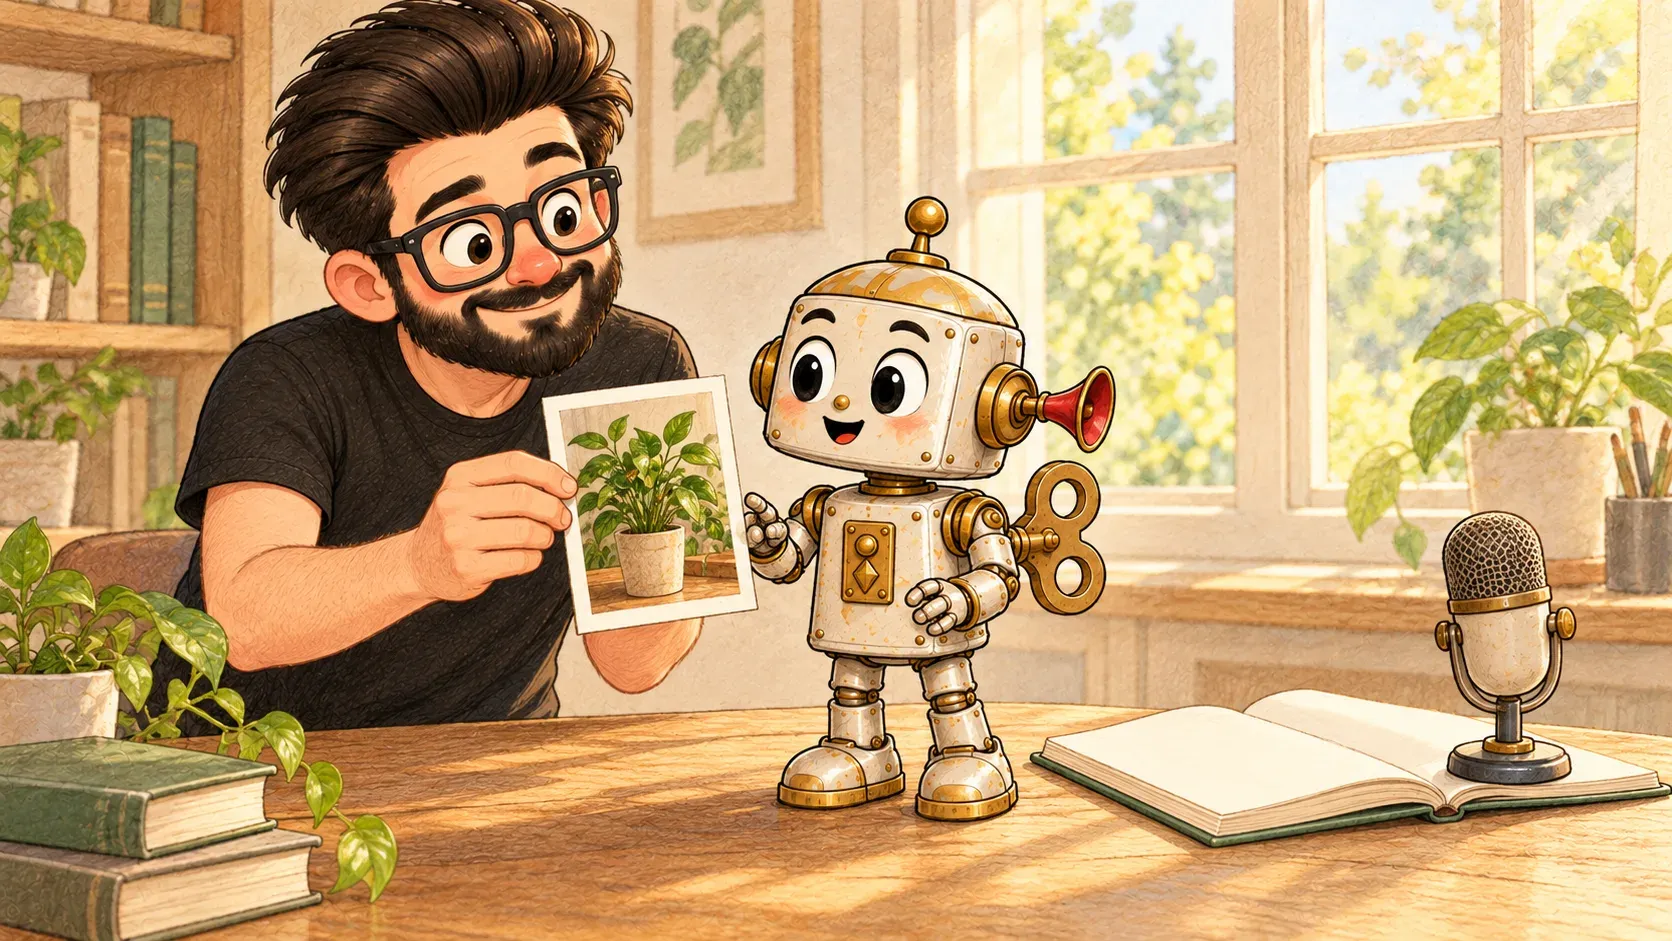

Early chatbots could only read text. Now you can show them a photo or talk to them out loud. That's multimodal.
Imagine an assistant who could only read notes you slipped under the door. Useful, but limited. Now imagine one who can also look at what you hold up and listen when you talk.
That’s the difference. A multimodal AI can take in more than one kind of input: text, pictures, sound and sometimes video. “Mode” just means a type of information.
What it can do
- read a photo of a menu in another language and translate it
- look at a chart and explain what it shows
- listen to you speak and answer out loud
- spot what's wrong in a screenshot of an error
Making as well as reading
Some multimodal AIs can also create pictures, speech or video, not just understand them. That overlaps with generative AI.
What it isn’t
It isn’t perfect eyesight. It can misread small text, miscount objects or miss details. Double-check anything important.
Where the comparison breaks down
A person looking at a photo uses a lifetime of real experience. The AI has only learned from examples, so it can confidently describe things that aren’t there.
How the words fit together
An LLM reads text. A multimodal model also sees and hears. Both are kinds of generative AI.
Stuck with a confusing screen or error? Take a screenshot and show it to a multimodal AI. It's often quicker than describing it.
When you'll hear it
“It's a multimodal model.” It can take in pictures and sound, not just text.
“Just upload a screenshot.” Show the AI a picture of the screen instead of typing it all out.
“Use voice mode.” Talk to the AI out loud and hear it answer.
“Could people save time here by showing the AI a photo or document instead of typing it out?”
