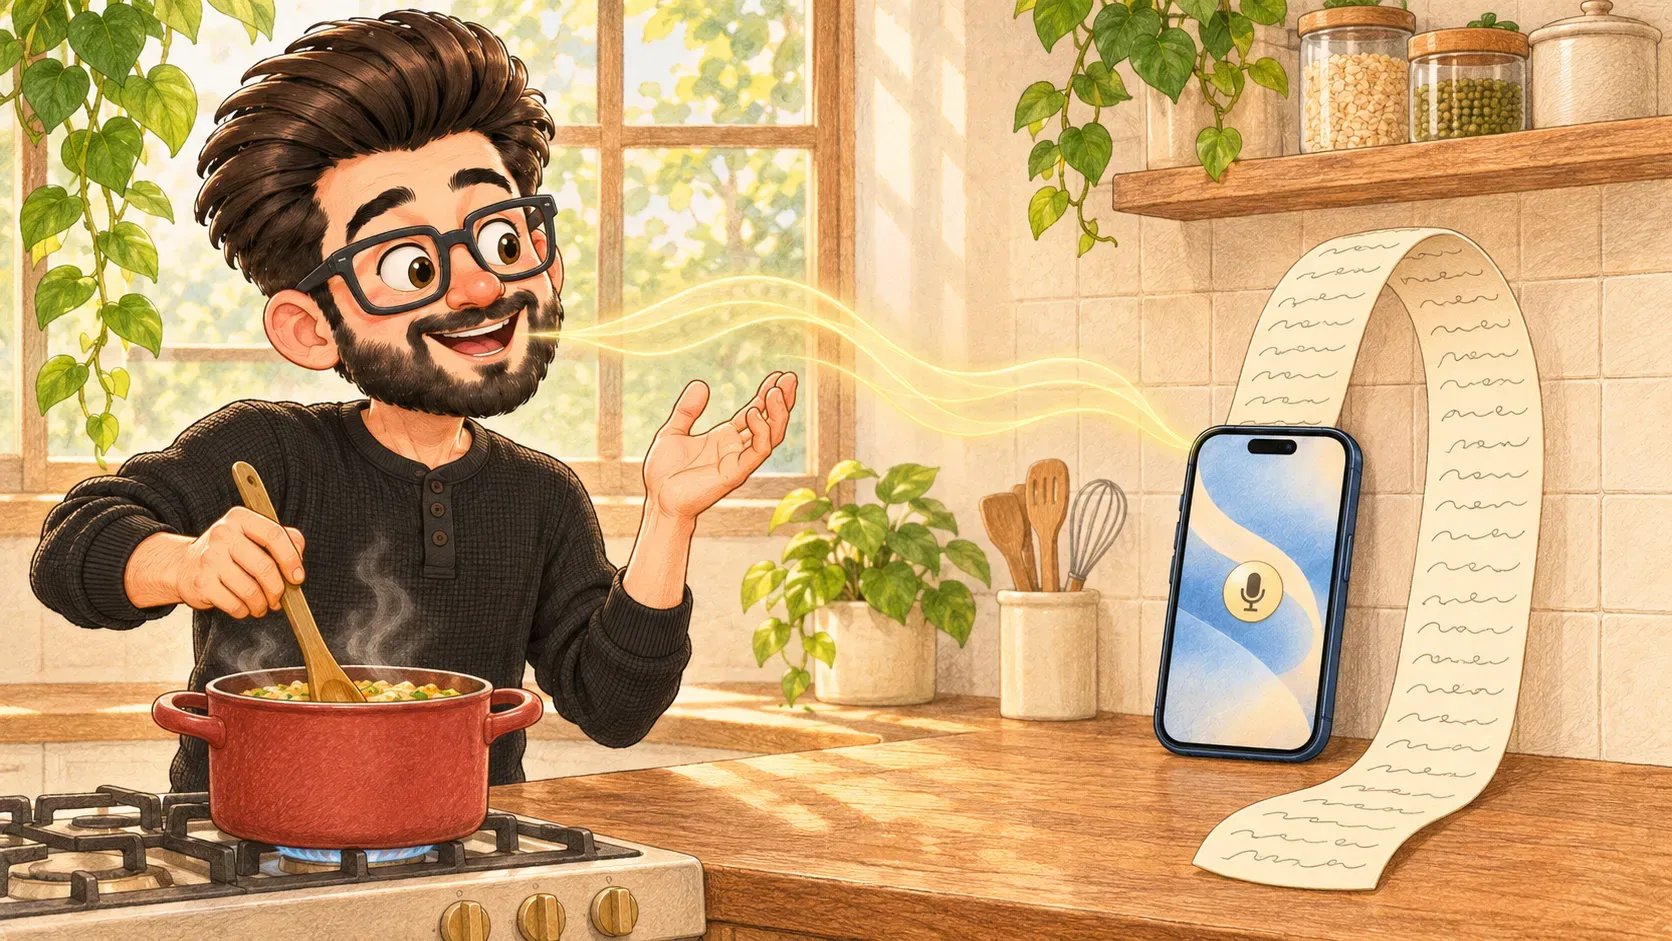

You say "remind me to call Mum at six" and your phone types it out word for word. Somewhere inside, a tireless typist was listening.
In a courtroom, a typist sits quietly and writes down every word anyone says, as fast as they say it. They never ask anyone to slow down and they never get tired.
Speech-to-text is that typist inside your phone or computer. It listens to talking and turns it into written words, as you speak or from a recording.
How it learns to listen
It’s a kind of machine learning. It was trained on huge amounts of recorded speech next to the words that were said. From that it learned which sounds go with which words, and which words usually come next. “Ice cream” and “I scream” sound the same; it picks the one that makes sense.
Where you meet it
- dictation: the microphone button on your phone's keyboard
- voice assistants: Siri, Google Assistant and Alexa hear you first
- captions: subtitles on videos and video calls
- meeting notes: apps that write up who said what
Where the comparison breaks down
A good typist asks “sorry, who?” when they miss a name. Speech-to-text just guesses and carries on, so it can confidently write the wrong word. It also doesn’t understand what it writes: it turns sounds into words, and another tool has to make sense of them.
How the words fit together
Speech-to-text runs on a neural network trained with machine learning. Its words are often handed to an LLM to answer or summarise. An AI that takes in voice, pictures and text at once is called multimodal.
Speech-to-text gets names, accents and noisy rooms wrong more often. Read it back before you send a message or share meeting notes.
When you'll hear it
“Just dictate it.” Say it out loud and let your phone type it for you.
“The call has live captions.” What people say appears as words on screen while they're talking.
“I'll send you the transcript.” A written copy of everything that was said in the meeting.
“Would people rather read a summary of this meeting than watch the recording?”
